Building scalable data processing pipelines
As we wrap up the first week in the new year, we are excited to announce the first set of upgrades coming to Heimdall. Below is a quick summary of the latest upgrades to Heimdall:
- Standardization of unstructured product design (UI only)
- Migration of Heimdall ML data processing to polars
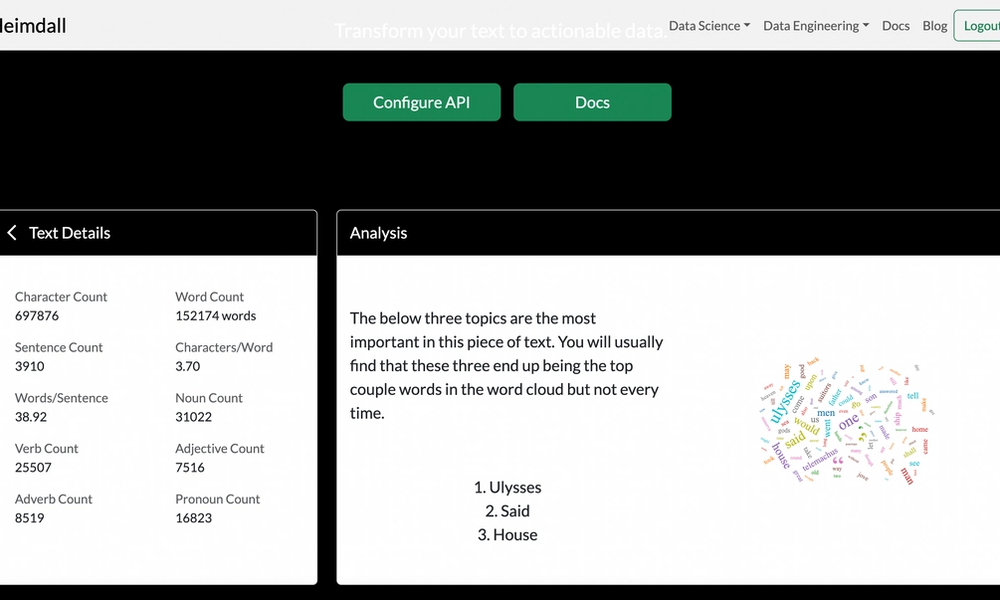
In just a week, we were able to make the experience across all the unstructured products the same. We really liked the grid layout design of Heimdall Point, so we decided to apply the same layout to the rest of the products.
Scaling Heimdall ML's Data Pipeline
In the fast-evolving landscape of data science and analytics, optimizing data processing pipelines is essential. Recently, our team decided to migrate our existing code base from Pandas to Polars, an innovative DataFrame library written in Rust, designed for high-performance data manipulation. The motivation behind this shift was to improve API endpoint response times by harnessing the power of parallel processing and taking advantage of the speed and memory efficiency that Polars offers.
The migration process began with a comprehensive evaluation of both Pandas and Polars, weighing their strengths and weaknesses. While Pandas has long been a staple for data science in Python, Polars caught our attention due to its Rust foundation, which enables it to leverage multi-threading for accelerated computations. As we navigated through the migration, we discovered that Polars not only excelled in handling large datasets but also exhibited remarkable performance improvements in tasks involving complex operations. The seamless integration with Arrow, a cross-language development platform for in-memory data, facilitated smooth interoperability and data interchange between different systems, with room for potential expansion in the future.
One of the key advantages we observed during the migration was the ease with which Polars allowed us to parallelize our data processing workflows. The library's ability to distribute computations across multiple threads drastically reduced processing times, leading to an improvement in API performance of around 40%. As we fine-tuned our data processing pipeline with Polars, seeing this remarkable boost in overall efficiency validated our decision to embrace this cutting-edge DataFrame library. The migration not only improved our existing codebase but also opened doors for building and improving Heimdall in the coming years.
Heimdall – Harness the Power of ML
Heimdall provides the data Infrastructure to modernize your data platform. Heimdall helps to build incredible user experiences that are powered by machine learning. It offers quick and efficient model building with even quicker model deployment. Heimdall allows your teams to quickly ideate and build out ML products 80% faster.
Heimdall scales from weekend projects to enterprise needs. Contact us today to be ready to compete in the digital age.