Inside Social Media Recommendation Systems: How Modern Feeds Decide What You See
Social media feeds are no longer simple chronological streams. Each feed is powered by recommendation systems that are designed to predict what content will be most relevant to each user at a specific moment. These systems rely on large scale data processing, behavioral modeling, and machine learning to rank and deliver content in real-time.
The Foundation: What Recommendation Algorithms Do
At the core of a social media feed is a learning-to-rank algorithm. Instead of simply displaying content, the system assigns a score to each post based on its predicted relevance to the user. This value is inferred from patterns in historical behavior and content characteristics.
Rather than relying on a single model, most platforms use a multi-stage pipeline, Early stages focus on narrowing down a large universe of possible posts, while later stages apply more refined models to estimate engagement and relevance with greater precision. The end result is a ranked list that reflects both long term user interests with immediate relevance.
This shift from chronological ordering toward predictive ranking fundamentally reshapes how content is delivered. The feed becomes a personalized experience that continuously adapts to each individual instead of a shared sequence seen by everyone.
Candidate Generation: Building the Content Pool
Before the ranking begins, the system must decide which posts are eligible to be considered. This phase, known as candidate generation, focuses on gathering a broad set of relevant content without worrying about order.
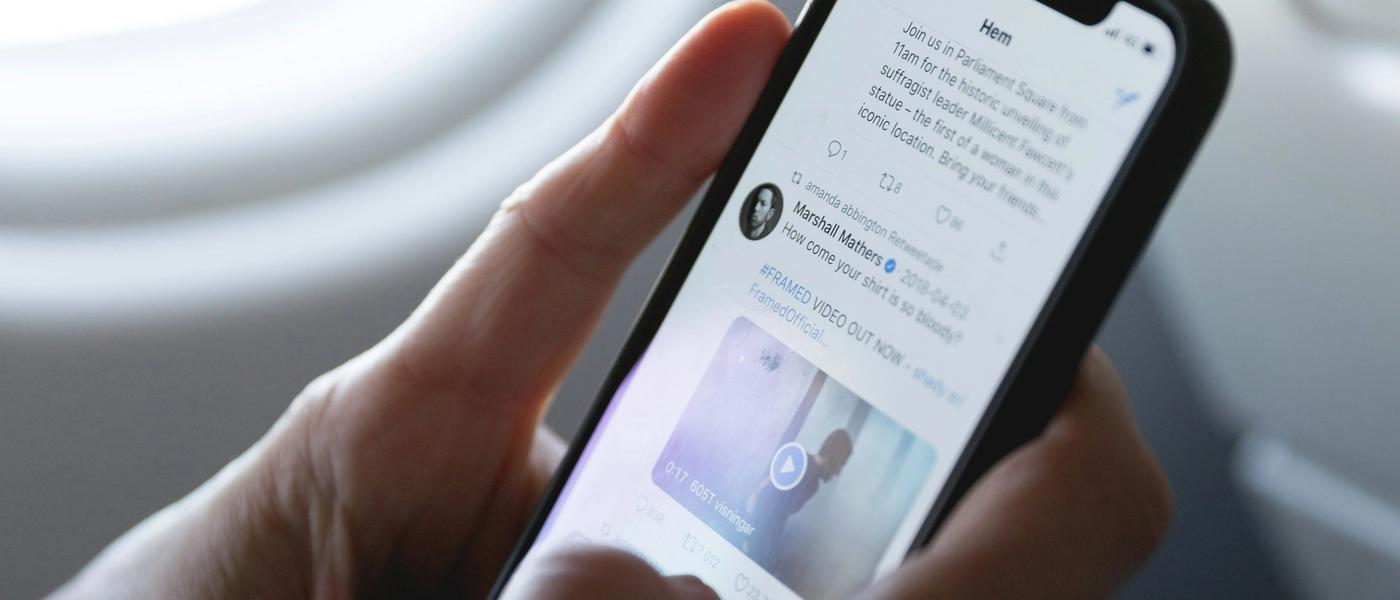
For example, on a platform such as Twitter/X, candidates may come from accounts a user follows, posts engaged with by people in their network, or content that aligns with topics the user has recently shown interest in. Trending or high velocity posts may also be added to introduce exploration and freshness.
From a machine learning perspective, this state prioritizes recall over precision. The goal is to capture a wide range of relevant options and allow later models to refine the ranking. Methods are used to surface relationships between users, authors, and topics at scale
Ranking and Engagement Prediction
Once candidates are collected, the system converts raw activity into structured features that models can actually use. These features describe the user, content itself, the author, and the surrounding context.
User features reflect patterns in behavior, such as past interactions, recurring topic interests, and relationship strength with certain authors, Content features describe what the post is about, how recent, and whether or not it includes media, and Author features help the system understand relevance and reliability.
From there, prediction models estimate how likely different outcomes are. These can include engagement actions such as likes or replies, deeper signals such as dwell time, as well as negative indicators such as quick scrolls. Each prediction contributes to a composite score that represents the expected value of showing that content to the user.
As a result, the ranking is not driven by popularity alone. It is based on the likelihood that a specific person will find the content relevant or worth engaging with.
Rule Layers, Constraints, and Safety Filters
Once content has been scored, another layer of logic is applied before the final feed is displayed. This layer exists because ranking purely for engagement can quickly lead to repetitive or low-quality experiences. The system has to balance relevance with broader goals.
Ranking adjustments may reduce overexposure to the same author, promote newer content, or ensure topic diversity. Safety and policy checks also ensure content is meeting platform standards.
These rules help shape the final feed into something that feels balanced and coherent. What users see is not just the direct output of a model, but the result of product decisions layered on top of machine learning predictions.
Continuous Adaptation Through Online Learning
A key characteristic of modern feed systems is that they are constantly learning. The ranking process does not end once content is shown. Every interaction becomes feedback that influences future decisions.
If a user engages with a new topic, the system detects that shift and adjusts ranking accordingly. Recent activity can temporarily carry more weight than older behavior, allowing the feed to respond quickly to shifts in interests. Likewise, negative signals quickly reduce similar content in future rankings.
This ongoing feedback loop makes the feed dynamic, rather than static. Over time, it reflects both long-term preferences and immediate intent, which is why social media experiences can change rapidly from one session to the next.
Conclusion
Modern social media feeds are best viewed as machine learning pipelines built to rank content while balancing several objectives at once. They gather potential posts, convert user behavior into structured signals, predict engagement outcomes, apply ranking constraints, and continuously learn from user feedback.
Twitter’s feed is a large-scale example of this architecture, but the same approach exists across many of the major platforms. In the end, what users see is the result of continuous optimization rather than simple ordering. Every interaction shapes the user’s own future, as the system evolves alongside the user.